
Each time you employ an internet site like Google or ChatGPT, your browser and a set of backend providers have an extended and surprisingly candid dialog about what you requested for. That dialog sits in plain sight within the Community tab of Chrome DevTools, a single F12 away, and most of the people by no means take a look at it. I’ve spent an unreasonable quantity of my time looking at this knowledge, and need to share what I’ve discovered with you.
Staring into this community abyss is what turned up a Google search exploit value a $13,337 bug bounty. It offered precise knowledge that gave some perception into how Google was working, together with not solely names of its parameters, however precise values for issues corresponding to Google’s site_quality_score, and Google’s personal rq_semantic_class. It additionally led me to be one of many first to find the completely different supply units ChatGPT pulls its outcomes from, and later, the freshness home windows it asks for when it searches, and proof that Reddit continues to be being learn by ChatGPT simply as a lot as ever, despite the fact that it has largely stopped being cited.
None of this wants an information science staff. It wants curiosity, a browser, and as of late an AI agent prepared to do the tedious bits. The purpose is just not that community knowledge is cool (it’s, mildly). The purpose is that understanding issues your rivals don’t is the closest factor search engine optimization has to a sustainable edge, and this is among the final locations these issues are nonetheless mendacity round free of charge.
Why Anybody Would Do This To Themselves
“Why?” is an inexpensive query, and one I believe most SEOs ask the lavatory mirror most mornings. Anybody that is aware of me, is aware of I take pleasure in enjoying video games, notably video video games, and I like a brand new problem of determining easy methods to win. That’s the recreation for me.
Working example, my finest pal lately taught me backgammon. As with all new recreation, I discovered the foundations after which misplaced repeatedly; studying the foundations of a recreation is just not the identical as understanding easy methods to play nicely. I believe I misplaced round 20 or 30 video games on the trot. They are saying 50. The determine is contested. Sooner or later throughout this run of humiliation, slightly than merely having fun with a nice board recreation like a well-adjusted grownup, I began determining easy methods to get small edges. For example, figuring out which distances on the board are literally reachable from two cube, and the way doubtless every one is. That issues, as a result of it tells you the place it is advisable to block your opponent and the place you’ll be able to safely go away a bit uncovered.
As I see it, search engine optimization works the identical approach. You’ll be able to study each finest apply within the information and you’ll nonetheless be dangerous at it till you will have expertise and discover ways to play the sport.
Optimization is the sum of cumulative positive factors and edges. Gaining this information permits you to stack 1% in your competitors over time in a approach that’s unattainable for that to mimic. This isn’t some “hack” method like a listicle they will copy in 10 minutes.
The Paper, Scissors, Rock Analogy
I found an analogy that I do know others discover helpful to clarify this strategy to shoppers or managers with the sport paper, scissors, rock.
Right here’s the situation:
Think about you’re enjoying limitless rounds in opposition to somebody whose said technique is to play rock each single time. What’s the optimum technique to play in opposition to them?
Most individuals instantly say “play paper each time” is the optimum technique to strategy this downside, and they might be mistaken. Whereas you’ll win the primary 5 or ten video games, your opponent, who is just not a houseplant, notices they’re shedding each recreation and modifications what they’re doing. This then steals any benefit you will have and places you again onto an excellent footing.
The optimum strategy is to play randomly however play paper barely extra usually. Your “optimization” will doubtless not be perceptible by your opponent, and with no apparent purpose to adapt, you slowly, quietly carve out an ever-increasing lead over time.
Blackhat Vs. Whitehat; Anticipated Worth (EV)
The paper, scissors, rock analogy basically encapsulates the argument between blackhat and whitehat search engine optimization approaches.
Blackhat search engine optimization completely works, and you may make a substantial amount of cash. Within the analogy we outlined above, blackhat search engine optimization is the “enjoying paper each time” technique. It’s efficient; your short-term anticipated worth (EV) is excessive, however you power the opposite aspect (Google, ChatGPT, whoever) to alter what they do, at which level your benefit evaporates and infrequently takes your area with it.
Whitehat search engine optimization is the “play paper barely extra” strategy, which focuses on producing worth with out anybody needing to alter the foundations, and to stack it up over time.
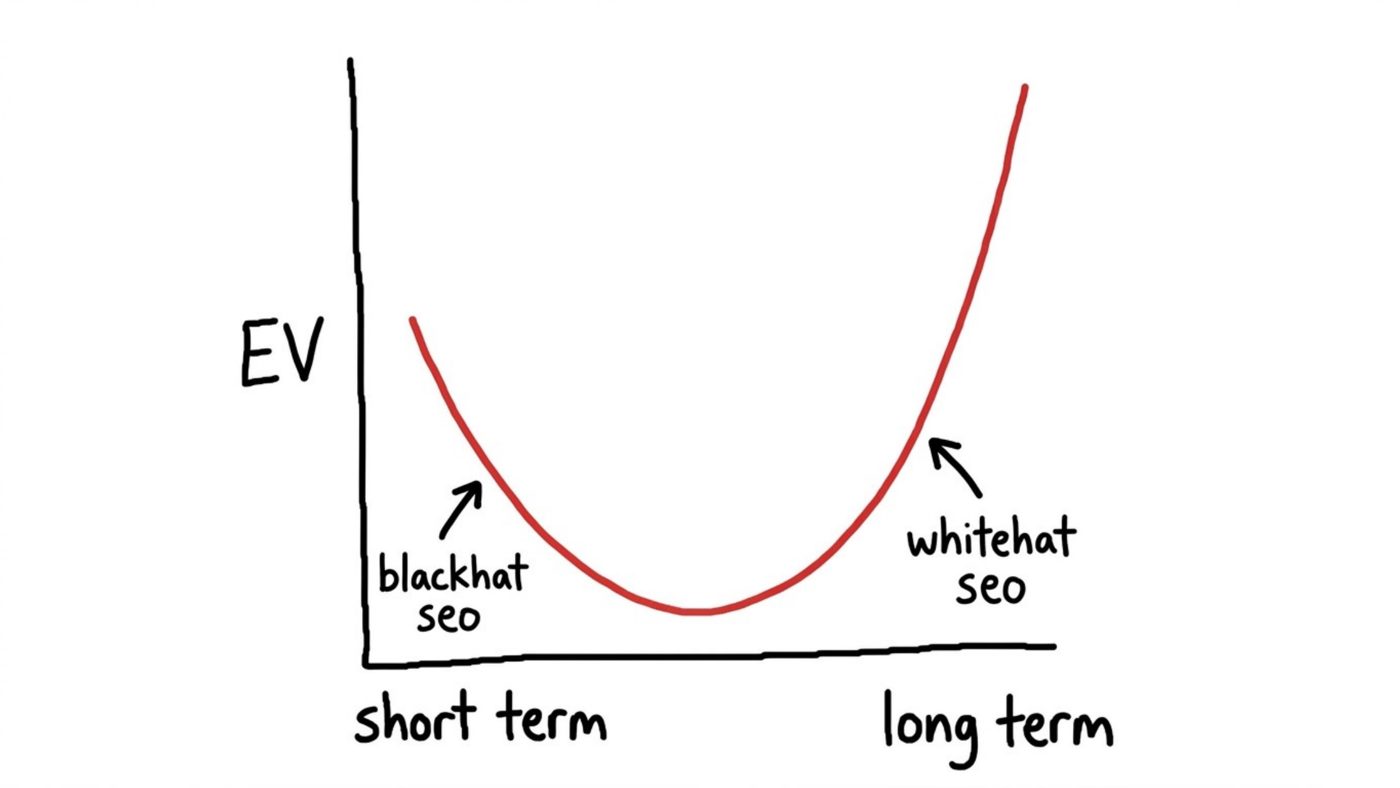
Community knowledge is among the finest locations I do know to search out this type of info to present you an edge over the competitors.
What Community Information Truly Is
If you use an online app like Google or ChatGPT, your browser is sending knowledge to backend providers and receiving knowledge again. The least technical approach I can describe it’s delivery crates touring to and from a warehouse.
Some crates have clear labels, so roughly what’s inside. Some have labels that make no sense in any respect. And a few you’ll be able to merely open, look inside, and infer what’s going on from the contents.
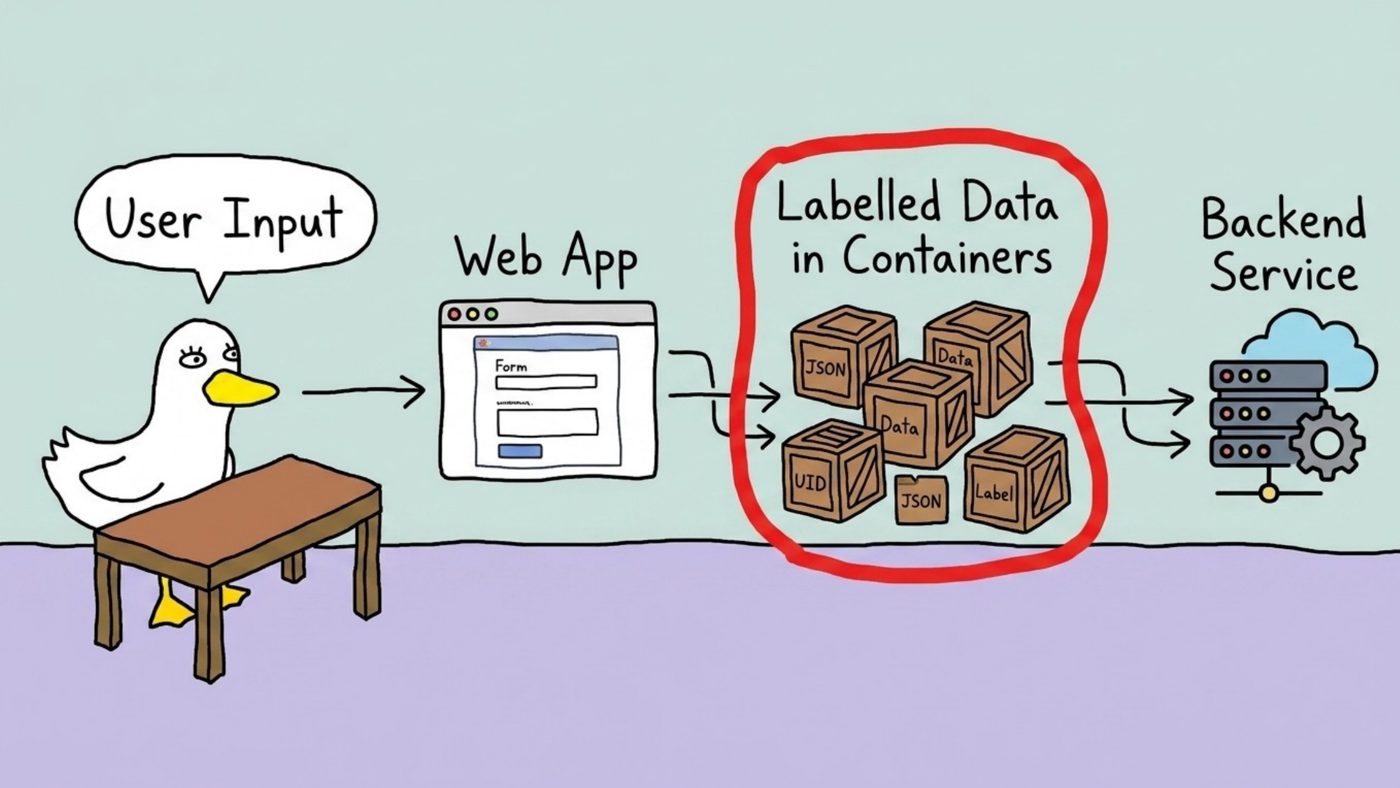
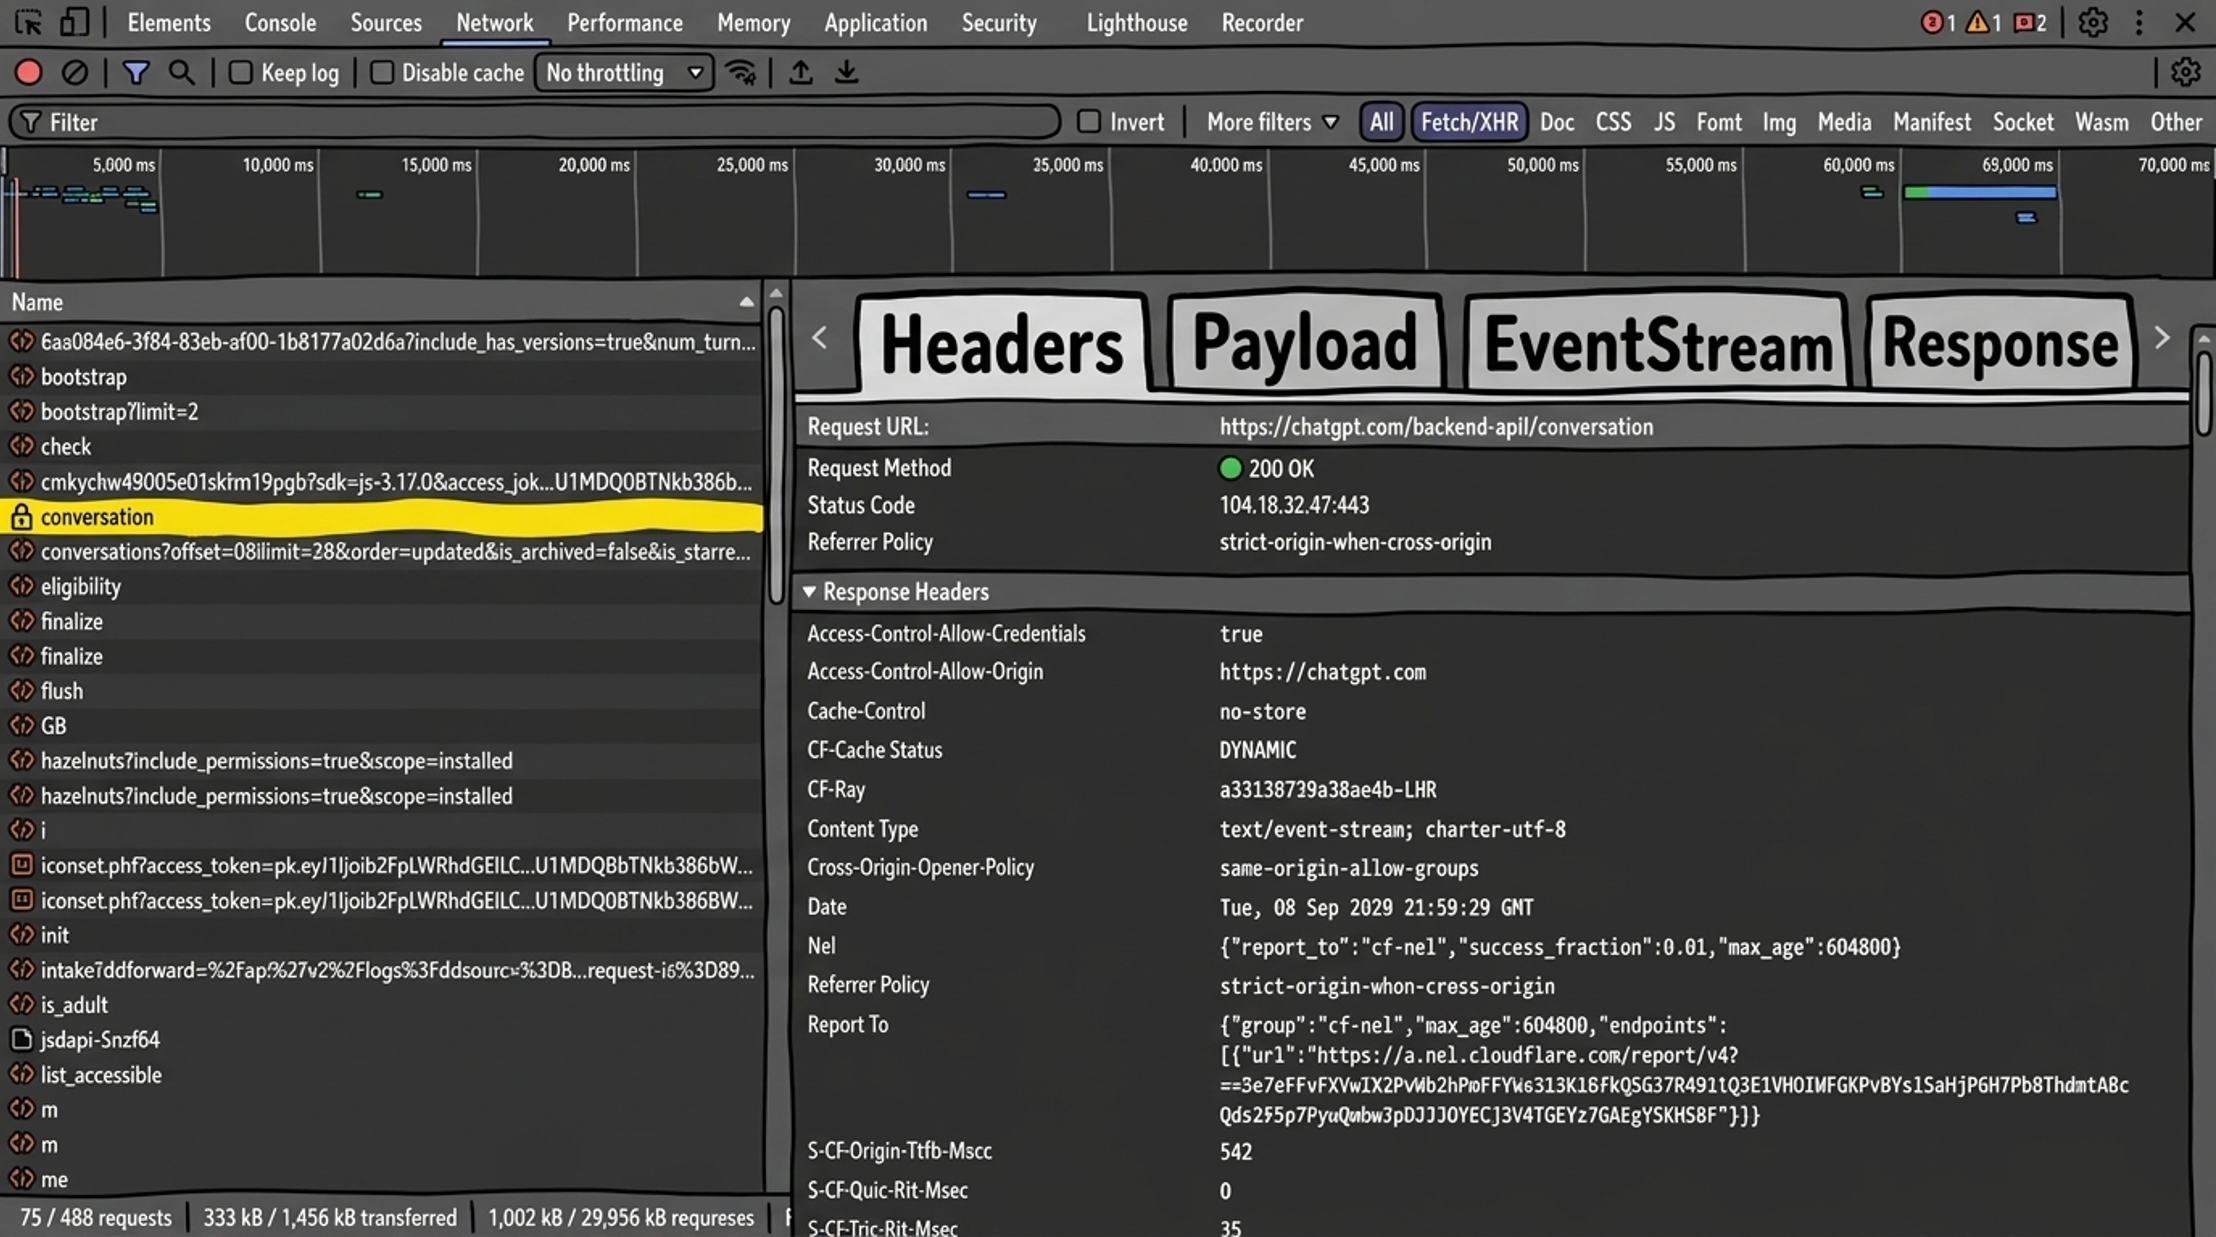
Getting at these crates is just not tough. Press F12, do a Google search or ChatGPT immediate, and you’re, for all sensible functions, within the Matrix. Click on the Community tab, filter to Fetch/XHR, and also you get a listing of requests. Click on on any certainly one of them, and also you get a set of tabs that look intimidating and are usually not:
- Headers: directions and metadata in regards to the request.
- Payload: what you despatched.
- EventStream: what continues arriving stay, as knowledge bounces forwards and backwards between your browser and the backend (ChatGPT makes use of this closely whereas it’s producing a solution).
- Response: what you bought again.
The rationale that is attention-grabbing slightly than merely nerdy is the way in which these techniques are constructed. Mario Fischer’s diagram of how Google’s rating techniques match collectively, assembled from the leaked Content material Warehouse documentation and DOJ trial reveals, makes the purpose visually: what appears from the skin like one monolithic search engine is definitely an enormous variety of small subsystems speaking to one another.
Methods on the entrance finish, like Google’s Superroot, have to know what you looked for, and so they pull in scores and alerts generated elsewhere within the stack. These scores and alerts need to journey someplace. Generally they journey by means of your browser, and generally no person remembered to take the labels off.
How We Discovered The Google Exploit (A Guide Instance)
A small confession earlier than we start. The rationale we spend a lot time doing that is that we run AlsoAsked, which entails a substantial amount of work with Google’s Folks Additionally Ask knowledge. I point out this so that you just choose me barely much less for the period of time I spend looking at Google’s community requests. Solely barely.
Whereas digging by means of request headers, we got here throughout a callback URL with a huuugee and attention-grabbing parameter string hooked up to it.
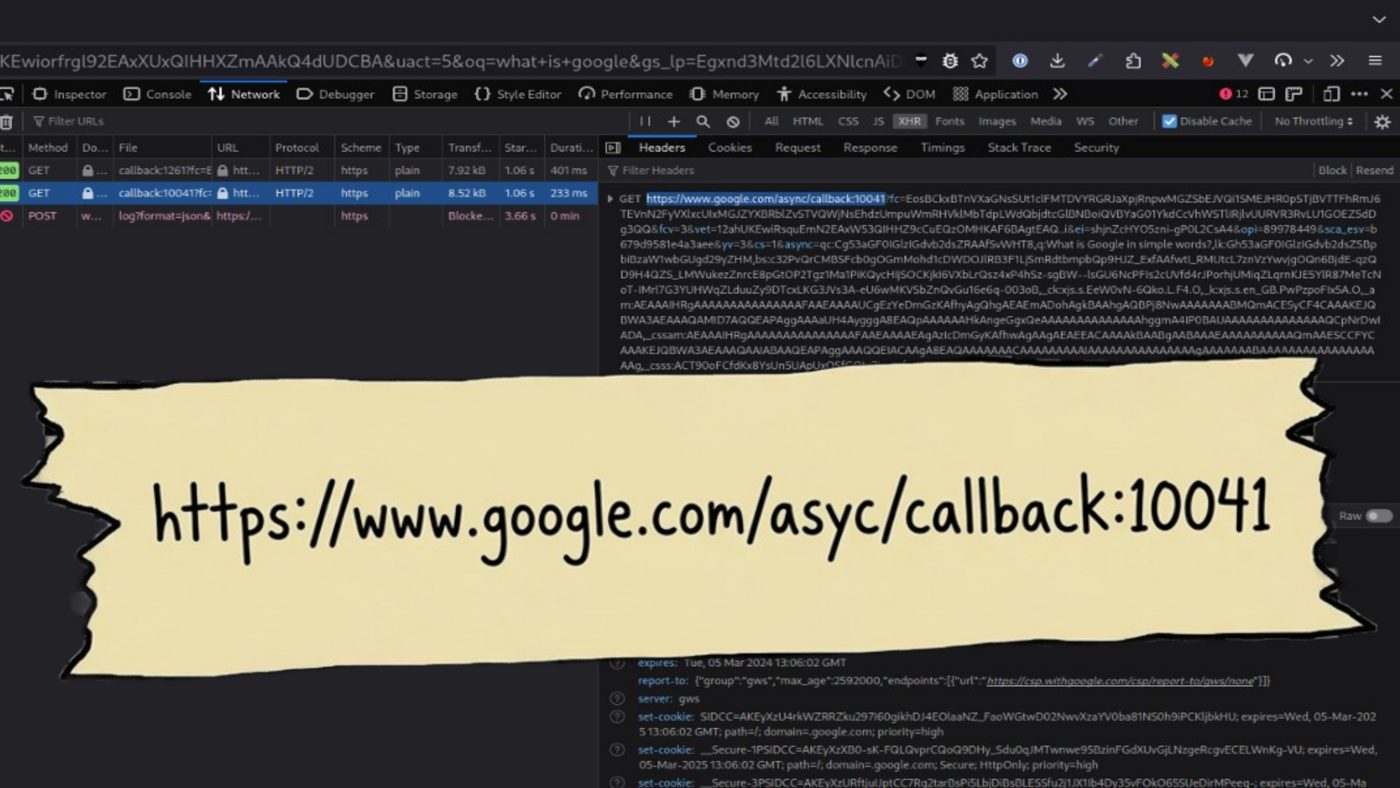
Naturally, the primary thought was to repeat the request right into a terminal, fireplace it off with curl, and see what Google despatched again. (This exercise can be a beneficial Tinder first date exercise; YMMV). We obtained a number of… stuff again, however it didn’t actually make a number of sense.
We seen a parameter referred to as _fmt, set to prog. We guessed, with no actual justification, that it’d imply “format.” For causes I genuinely can not now keep in mind, in what actual knowledge scientists would describe as “dumb luck,” puzzled what would occur if we merely deleted it.
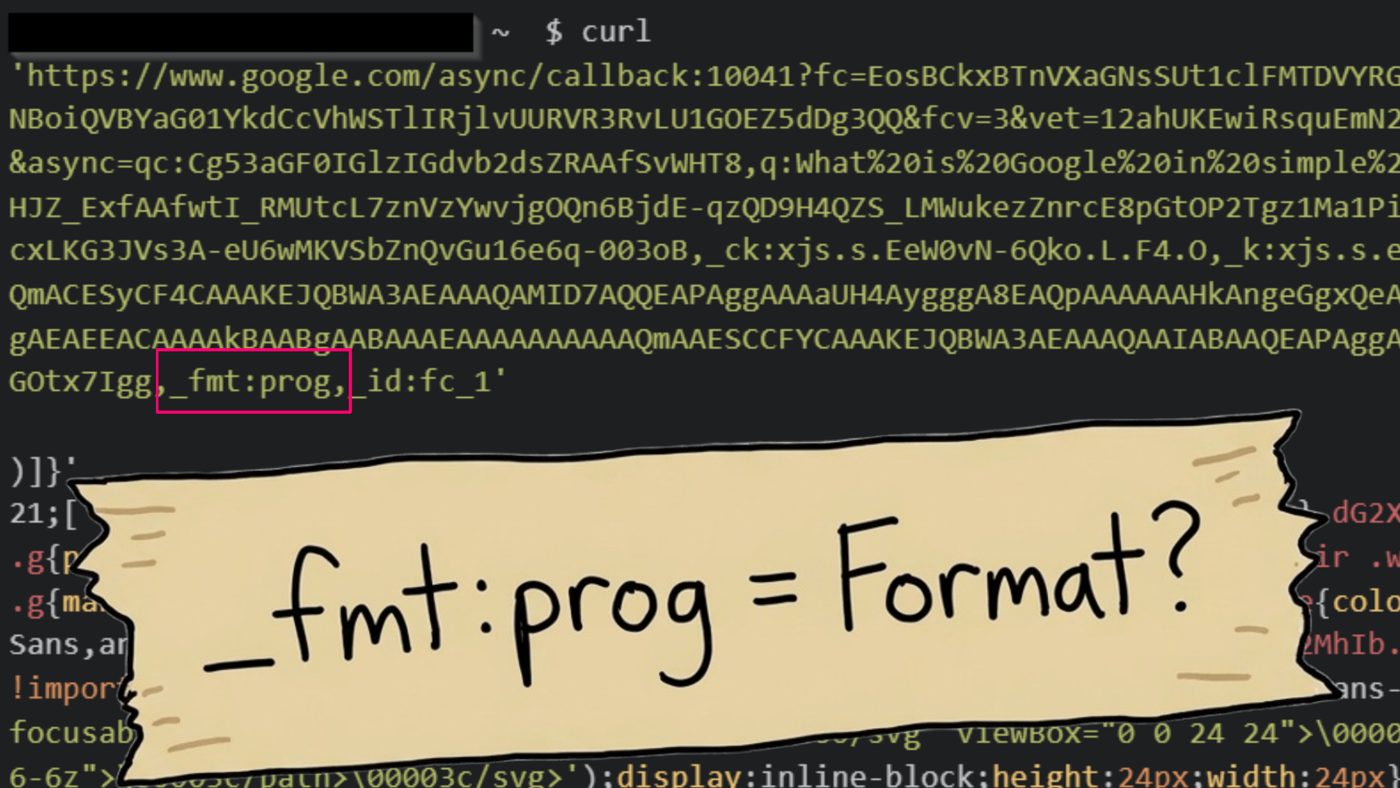
What occurred was that Google despatched again structured knowledge. Plenty of it. Web site high quality scores. Inverse doc frequency scores. When the web page was final considerably up to date, in epoch time. The server IP. All types of knowledge that Google very a lot didn’t intend us to have.
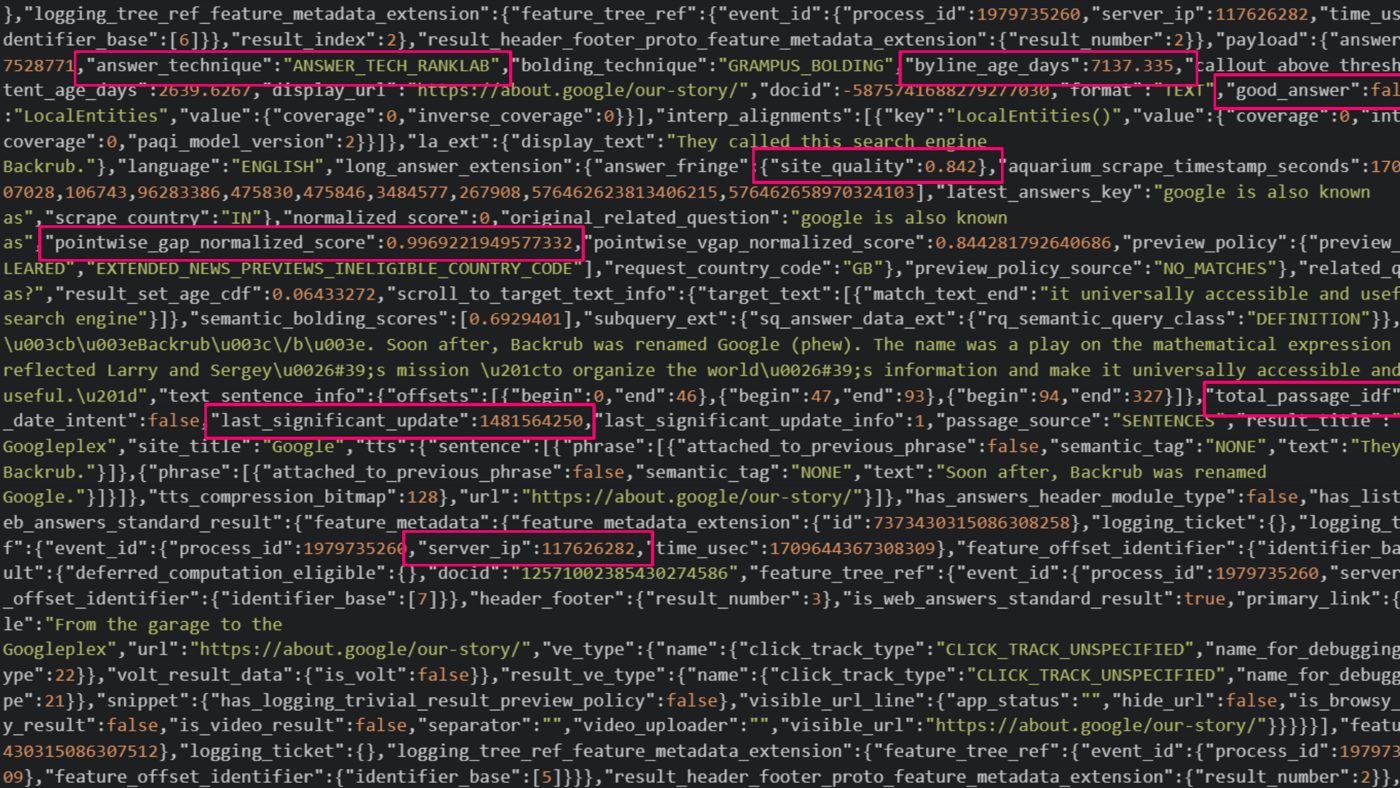
Which is how we ended up with a bug bounty from Google. We did report it, in equity. A couple of yr after we discovered it. We won’t dwell on that.
The Google Vulnerability Reward Program panel awarded $13,337.00, noting that “exploitation chances are excessive” and that the difficulty “certified as an abuse-related methodology with excessive impression.” I’ve chosen to take that as a praise.
Getting Worth From the Information
Whereas there was a number of direct worth in that knowledge, I need to decide a barely extra uncommon instance of the way it became one thing helpful.
One of many issues we seen whereas hoovering all the pieces up was that Google classifies just about each question into certainly one of eight “refined question” semantic lessons. Throughout a pattern of 4.8 million English queries, the distribution regarded like this:
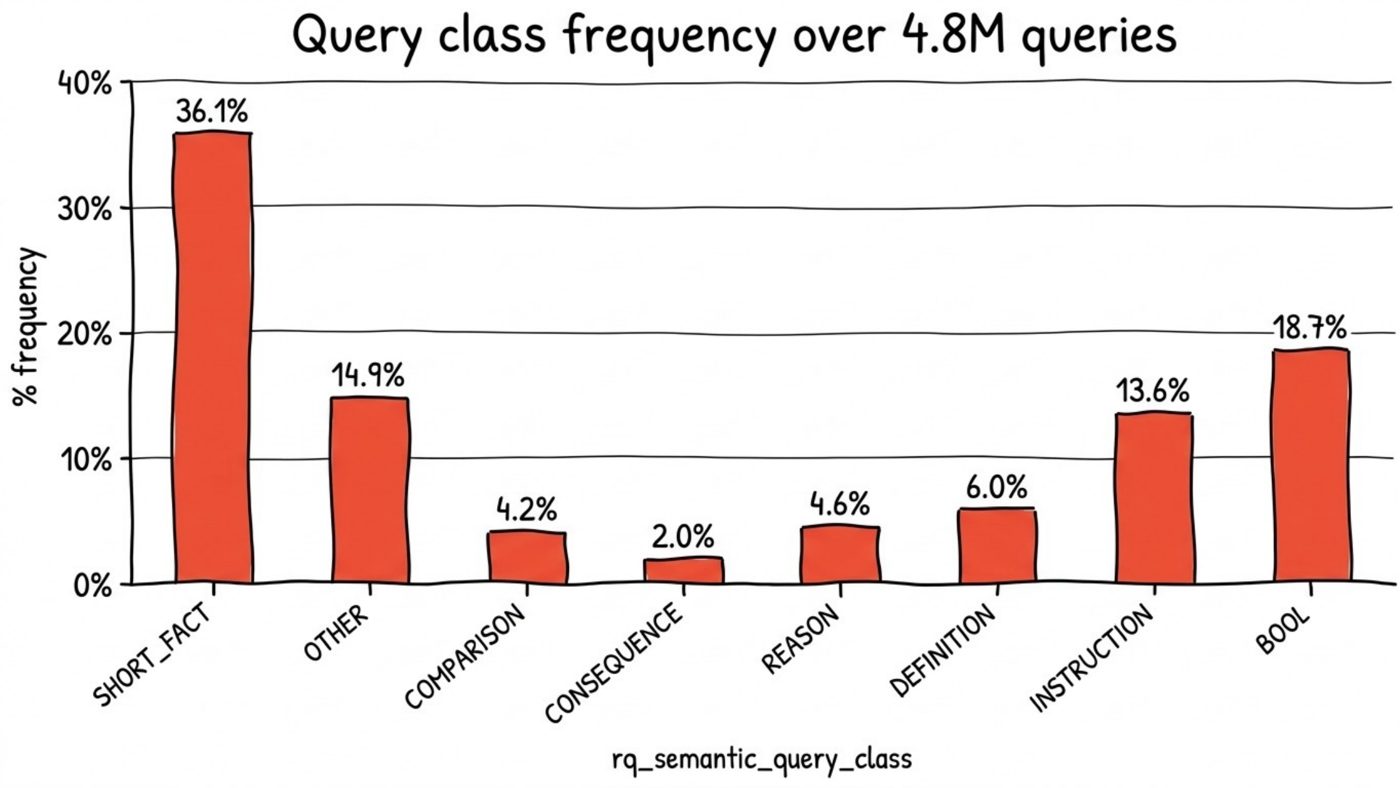
A pile of labelled knowledge like that’s precisely what it is advisable to prepare a classifier. I went to Hugging Face, the AI neighborhood and mannequin hub, and downloaded DistilBERT, a smaller, quicker model of Google’s BERT mannequin (40% smaller, 60% quicker at inference, and retaining round 96% of BERT’s efficiency). It’s sufficiently small to run by yourself pc, which is technically true within the sense that I managed to finish the fine-tuning based mostly on all 4.8 million queries and Google labels in about 50 hours on a gaming laptop computer (which was doing an excellent job heating my room).
The result’s QueryClassifier, which we put on-line free of charge. You give it any search question, and it predicts how Google goes to categorise it.
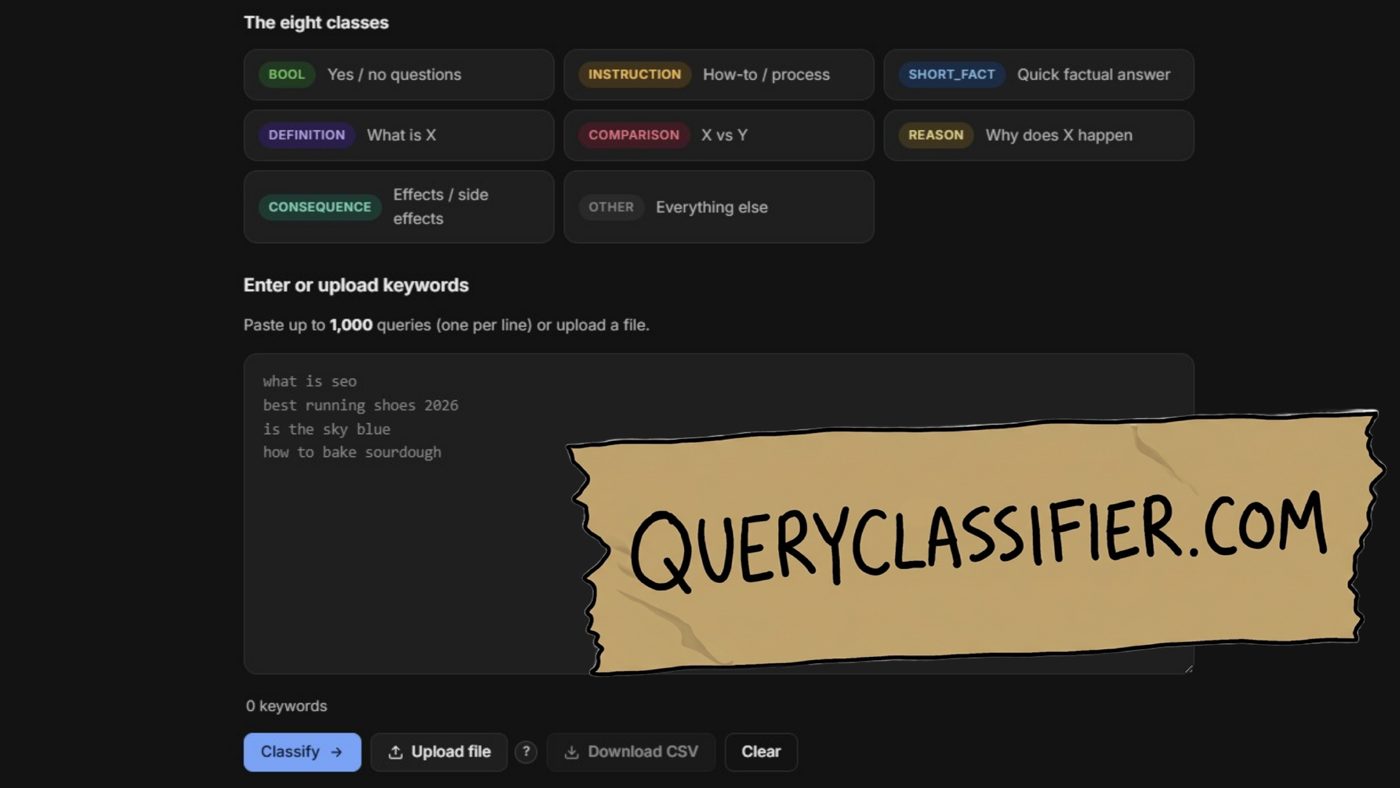
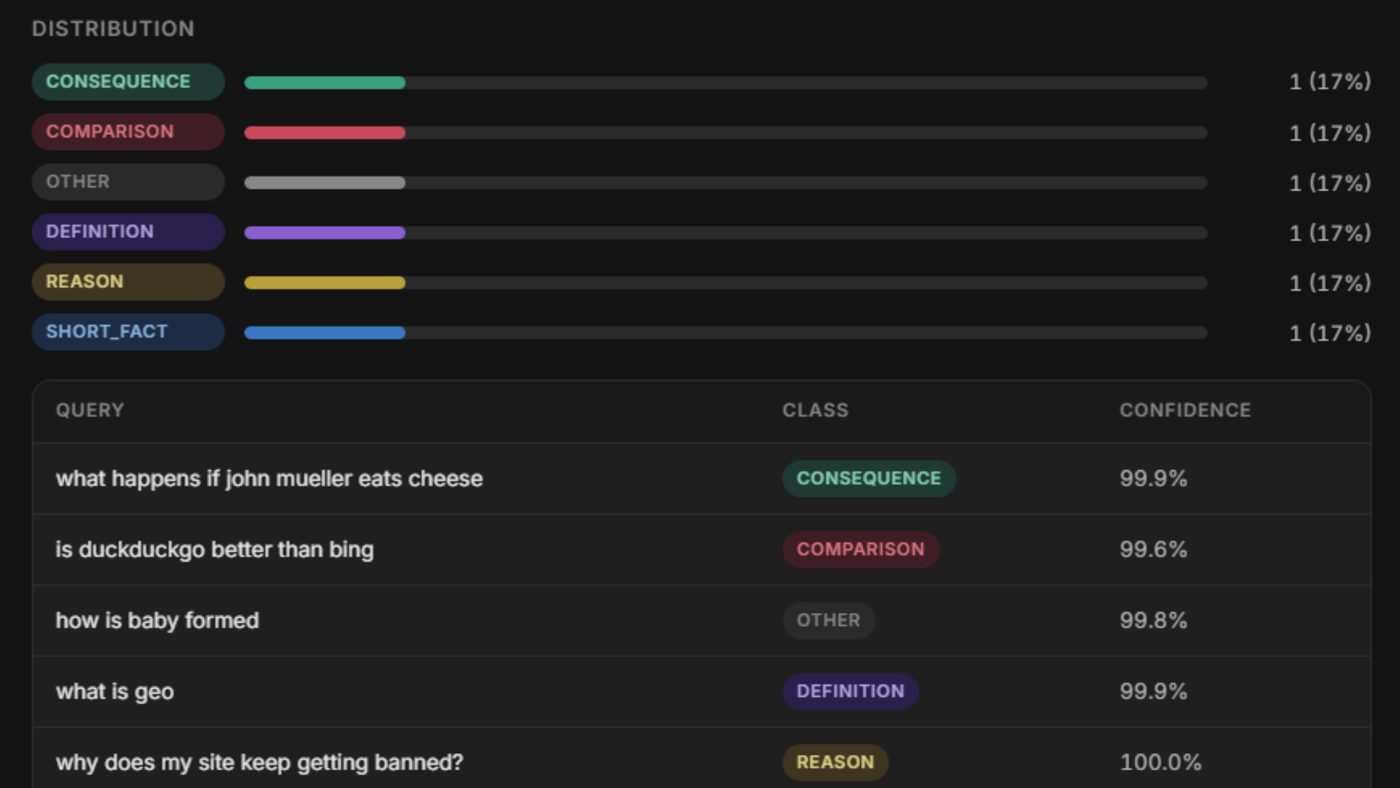
This output is extra helpful than it appears for a content material pipeline. Realizing the question class tells you what kind of content material Google is anticipating to reply it with, and there’s a robust correlation between question class and the SERP options Google chooses to indicate. So you’ll be able to know forward of time, and at scale, which options it is advisable to be optimizing for. You may as well discover out, with 99.9% confidence, that “what occurs if john mueller eats cheese” is a CONSEQUENCE question, which I contemplate a public service.
Getting ChatGPT Fan Outs First
I’ve been doing this type of handbook evaluation for years. Over a yr in the past, I used to be posting recommendations on easy methods to watch ChatGPT’s fan-out queries within the Community tab: Open the dialog request, take a look at the Response, and seek for search_model_queries. On the time, I don’t assume anybody else had that.
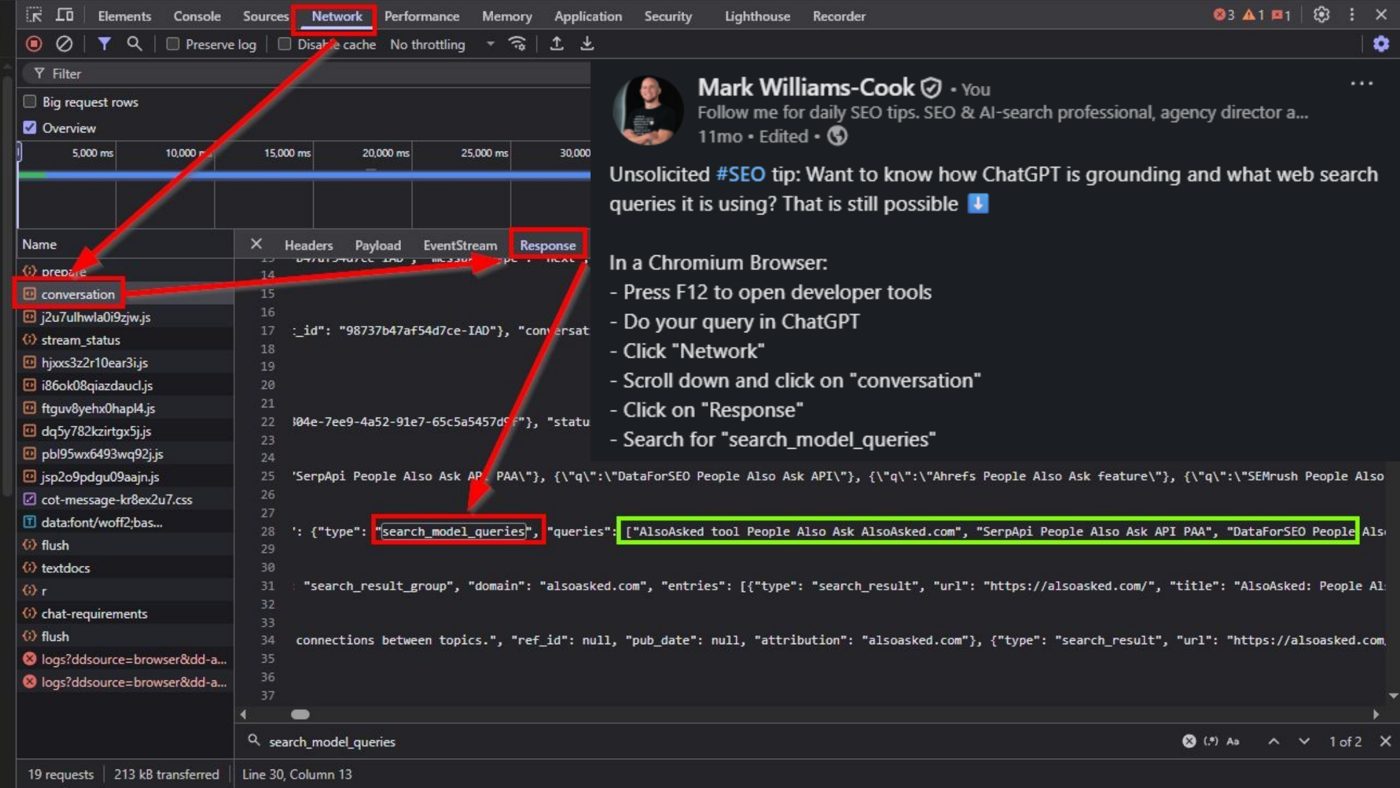
That particular trick not works, as a result of the format has since modified (extra on that shortly). However the precept stands. The attention-grabbing info is just not within the reply ChatGPT reveals you. It’s within the crates.
Now You Can Vibe Code Your Technique to This
Happily(?), we now stay in a world of vibe coding, which implies you not need to do all of this by hand.
My weapon of selection is Perplexity Laptop, Perplexity’s agent orchestration system. I gave it what Gen Z would describe as a “fairly beg” immediate. In essence, I’m telling Perplexity that I’m making an attempt to work out how ChatGPT works by analyzing its community knowledge in Chrome. I give it some examples of the forms of issues I’m on the lookout for (search_model_queries), and I need it to assist me run some searches, analyze what comes again, and determine the rest that may trace at how the system works.
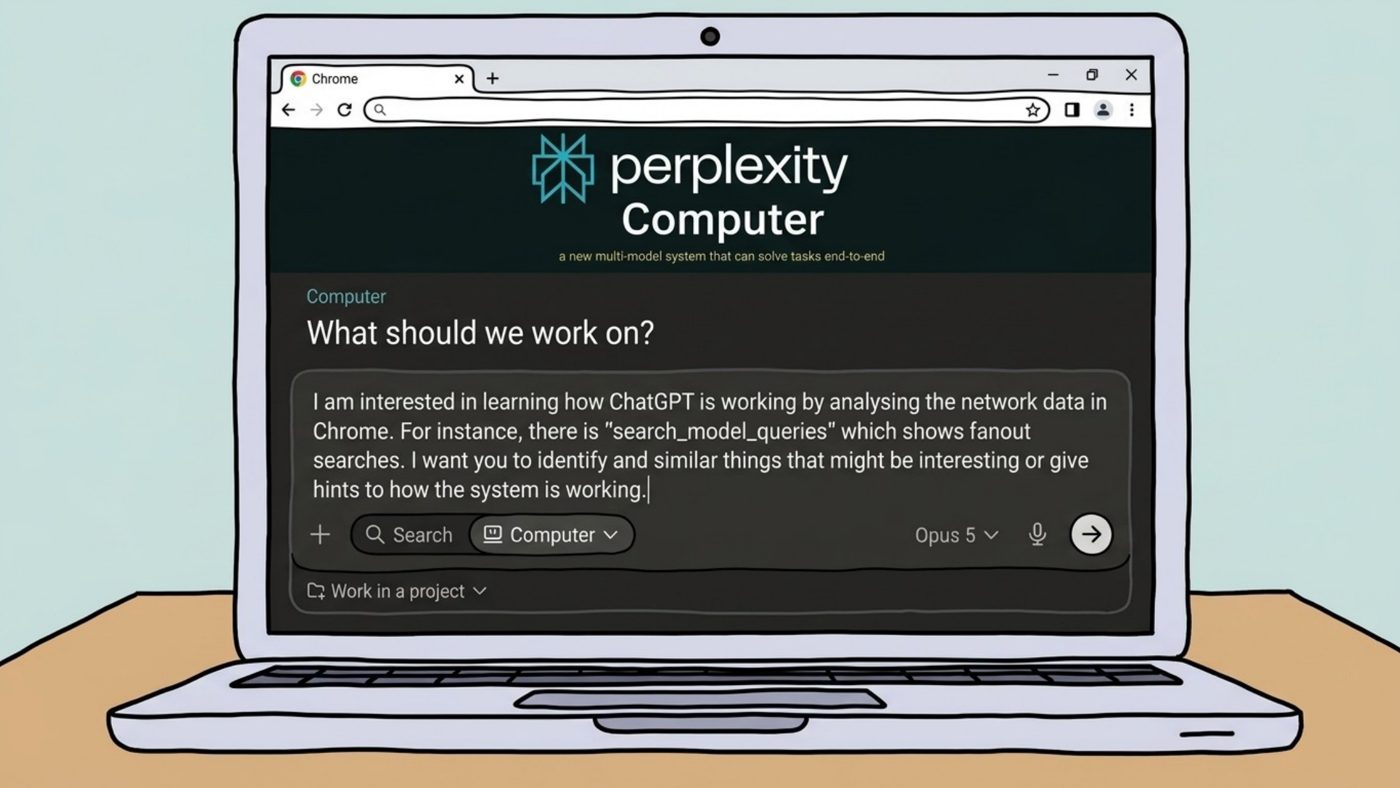
Perplexity was very adept at this process. Within the background, it used Playwright to fireside up actual Chrome situations, ran searches on ChatGPT, captured the community knowledge, and produced a twenty-something-page report that we might then have a dialogue about.
That’s how I used to be one of many first to find that ChatGPT was pulling its outcomes from completely different supply units, labelled in a result_source area:
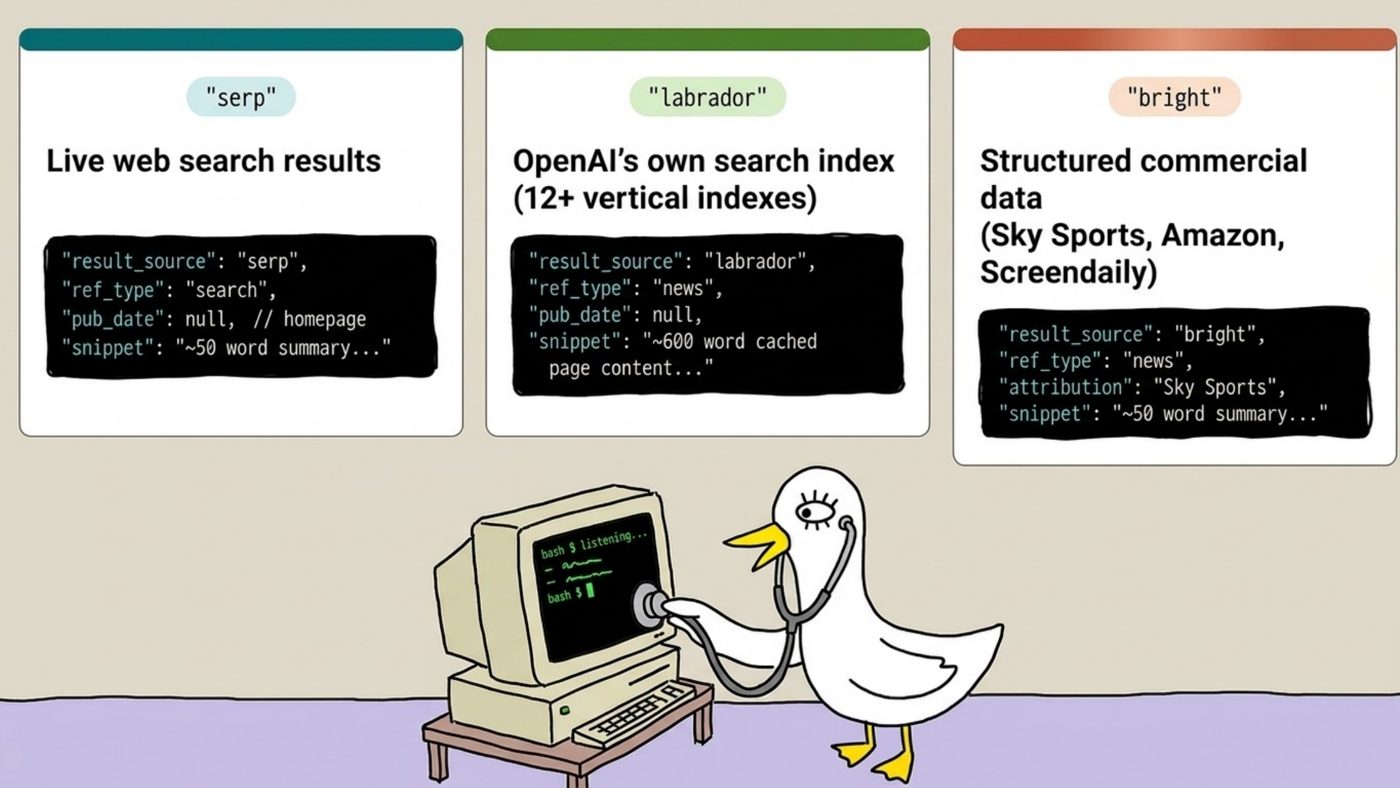
On the time, with the restricted dataset, I believed these to be:
- serp: stay net search outcomes, scraped from a search engine within the background. Basic retrieval-augmented technology.
- labrador: which I didn’t recognise on the time, and which seems to be OpenAI’s personal index.
- brilliant: which I imagine is Shiny Information, a supplier of structured business knowledge packs.
I ended up publishing this analysis earlier than I’d actually had an opportunity to dig into it for the noble purpose of blind panic. Metehan Yesilyurt had teased he had a giant reveal on LinkedIn round how ChatGPT works, and I had a horrible feeling I knew precisely what it was going to be about. So I messaged him to apologize upfront, defined I had been doing the identical analysis, and posted mine instantly. That is what passes for etiquette in technical search engine optimization.
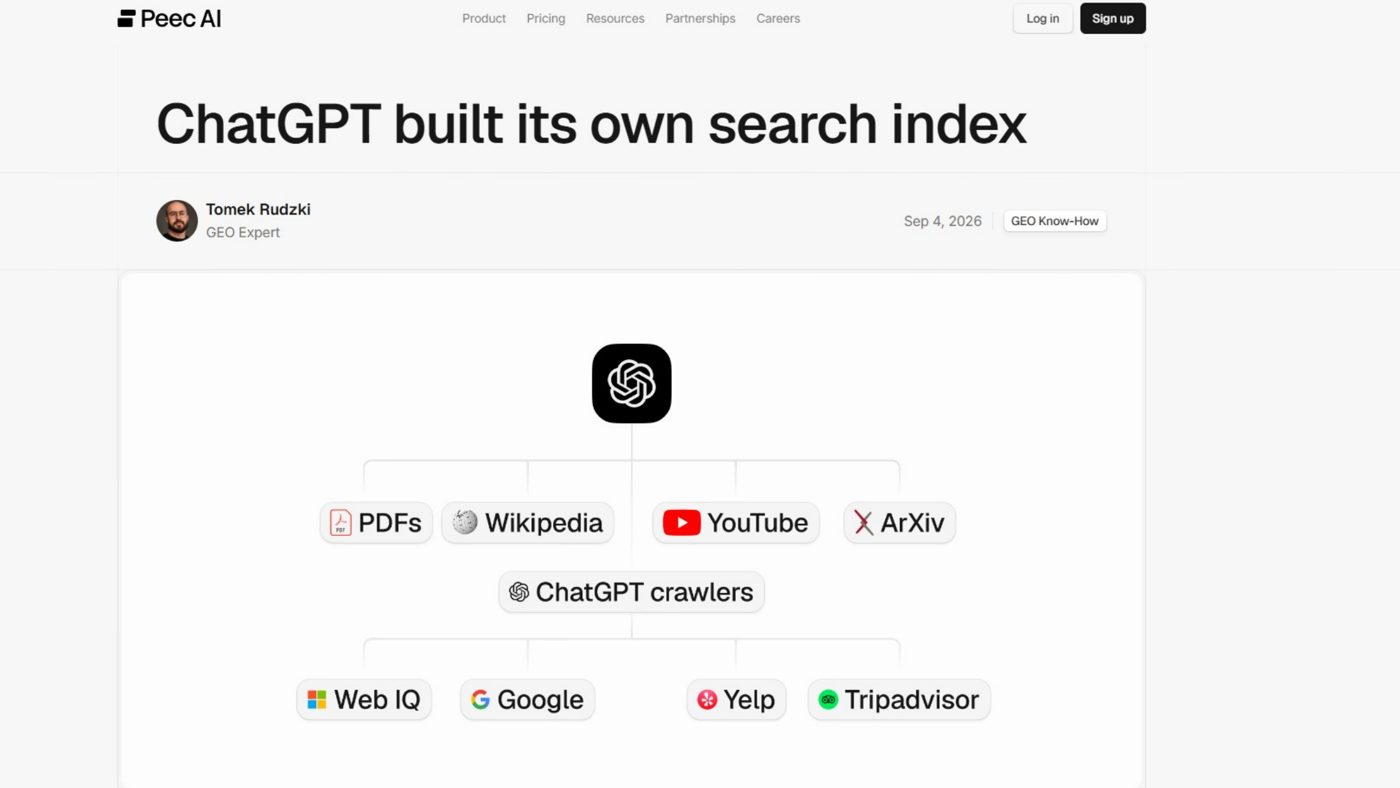
To be clear, folks have since finished a lot better, deeper work on this than I did. Tomek Rudzki‘s analysis for Peec AI discovered that result_source solely ever carried 4 values (Labrador, Shiny, Oxylabs and SERP) and that Labrador is just not a single index however a household of vertical indexes protecting the final net, PDFs, YouTube, information, arXiv, Wikipedia, native, finance, authorized, medical, procuring and pictures. If this topic pursuits you, learn that, and observe Metehan, who writes a substantial amount of good materials on it.
Getting Across the Scraper Bouncers
When you find yourself enjoying this type of recreation at scale, there’s a downside you’ll run into rapidly: getting blocked. Google blocks you. ChatGPT blocks you. Automated browsers pushed by vibe-coded scripts are usually not delicate, and the platforms have seen.
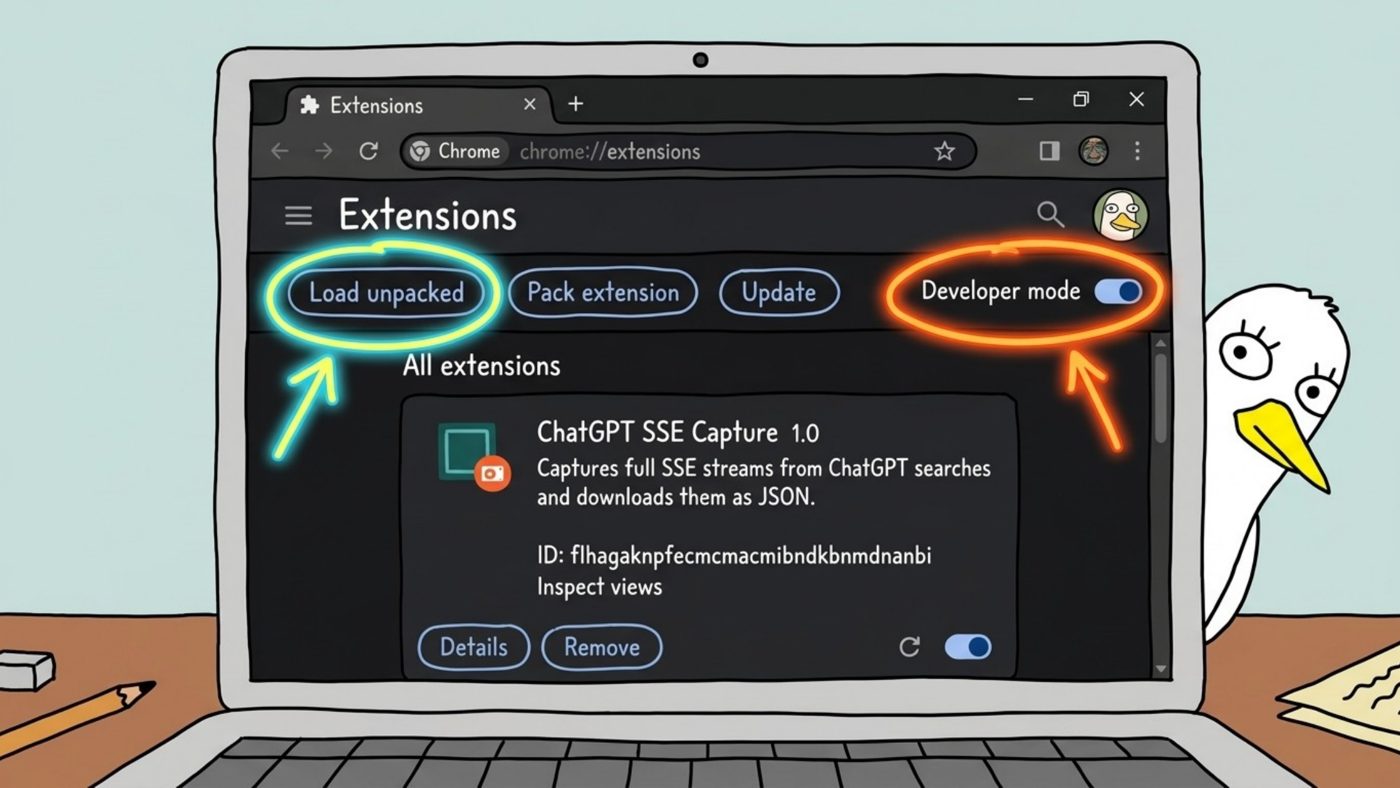
The workaround I landed on was to get Perplexity Laptop to construct me a customized Chrome extension to automate my native browser. This implies I might help with human checks; I might have straightforward management over which fashions, accounts, and settings I used to be utilizing (which all impression outcomes).
The cool factor is, you don’t want to publish it to the Chrome Net Retailer and wait for somebody to overview it. You go to chrome://extensions, swap on Developer mode, click on “Load unpacked,” and level it on the folder. That’s it. No hoops.
Other than pulling aside the community knowledge of ChatGPT, the extension “I” constructed features a “analysis mod” which lets me paste in a complete listing of prompts, then automates the browser for me: with repeats and gaps between runs, saving all the community knowledge that comes again. That permit me do that evaluation at a a lot bigger scale than poking at DevTools by hand.
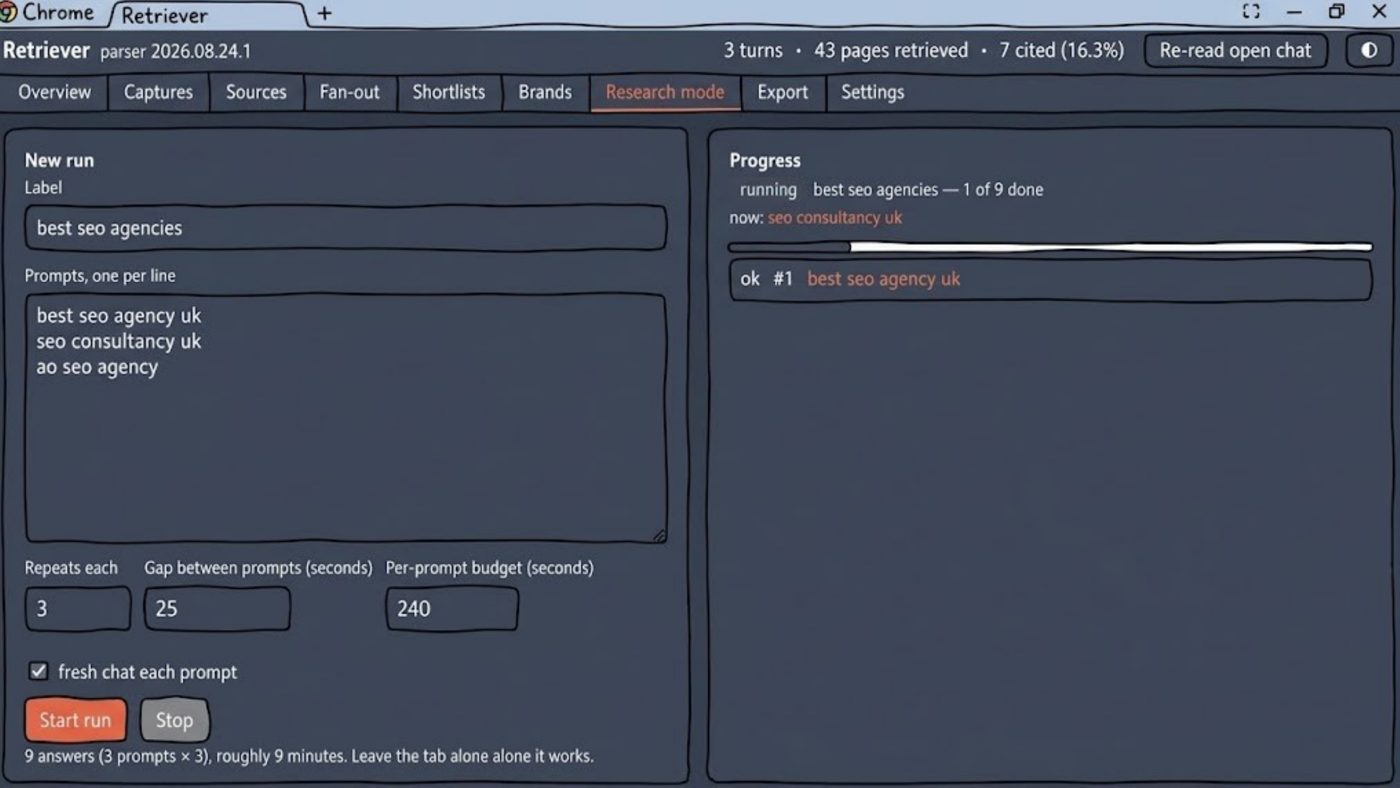
I used to be going to tidy up a model of this for public launch, however it turned out I by no means wanted to, as a result of my good pal Suganthan Mohanadasan had been doing very related analysis on the identical time and launched FanoutFox, a free Chrome extension that does basically what mine does, minus the majority checker, and does it extraordinarily nicely. It reads your individual ChatGPT session and reveals you the fan-out queries, the sources fetched, who obtained cited, and who solely obtained talked about.
What FanoutFox Information Confirmed
1. ChatGPT’s Freshness Home windows
Considered one of Suganthan’s findings is the kind of factor I might beforehand have anticipated to wish a leak to study. When ChatGPT runs a search, the community knowledge contains the question it ran adopted by a vertical pipe and a quantity. That quantity seems to be a time window, in days.
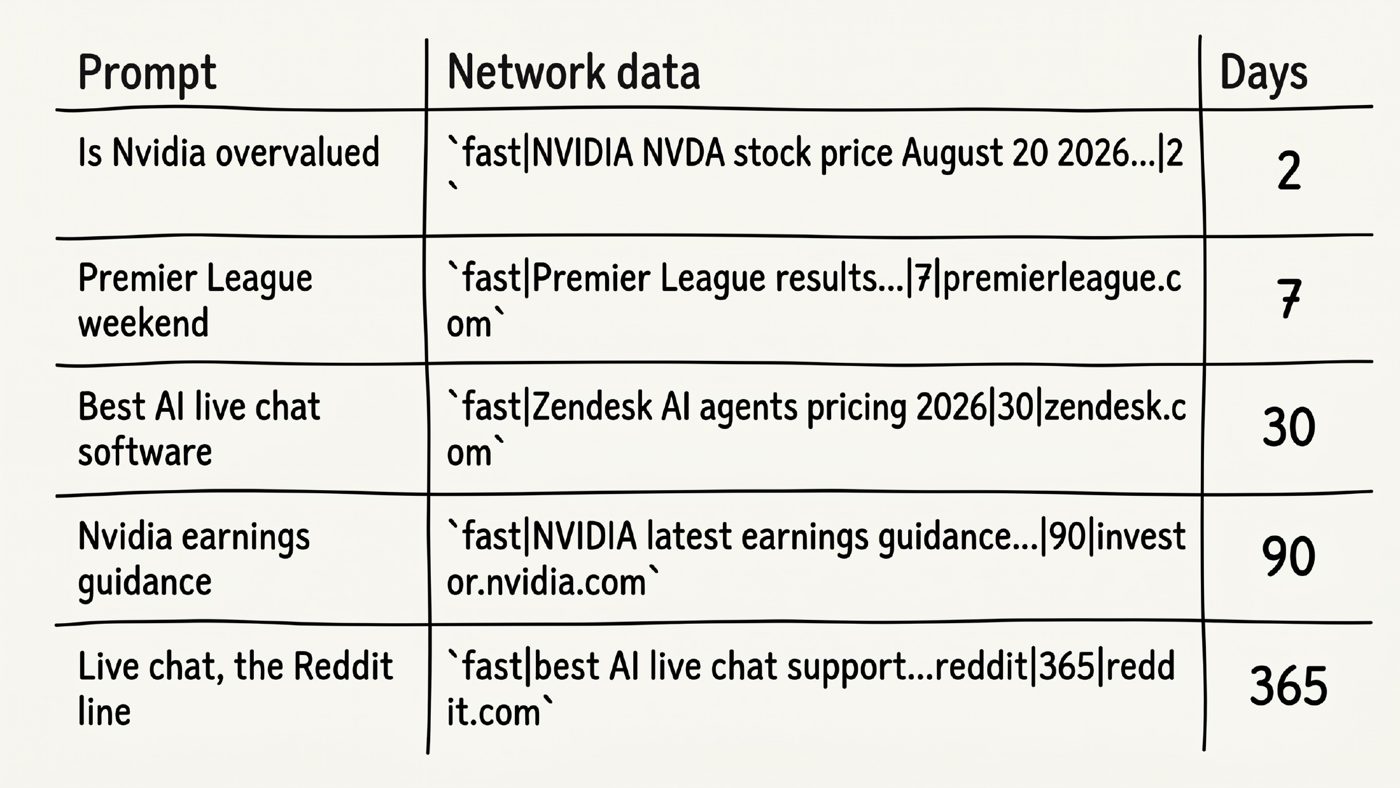
Ask whether or not Nvidia is overvalued and ChatGPT searches for inventory value info with a window of two days. Premier League weekend outcomes get seven. “Finest AI stay chat software program” will get 30. Nvidia earnings steerage will get 90. And when it goes taking a look at Reddit for stay chat assist opinions, it targets reddit.com particularly, with a window of twelve months.
There isn’t any scarcity of assured opinion within the business about how contemporary content material must be. This is among the only a few locations you will get an goal reply, from the system itself, in regards to the window it’s really trying in for a given subject. That may be a excellent start line for a content material pipeline: For this type of question, that is roughly how updated the knowledge needs to be to qualify in any respect.
2. Whether or not ChatGPT Is Even Looking out
FanoutFox may also let you know whether or not retrieval is occurring in any respect for a given immediate, or whether or not the reply got here fully from the mannequin’s parametric reminiscence, that means its coaching knowledge.
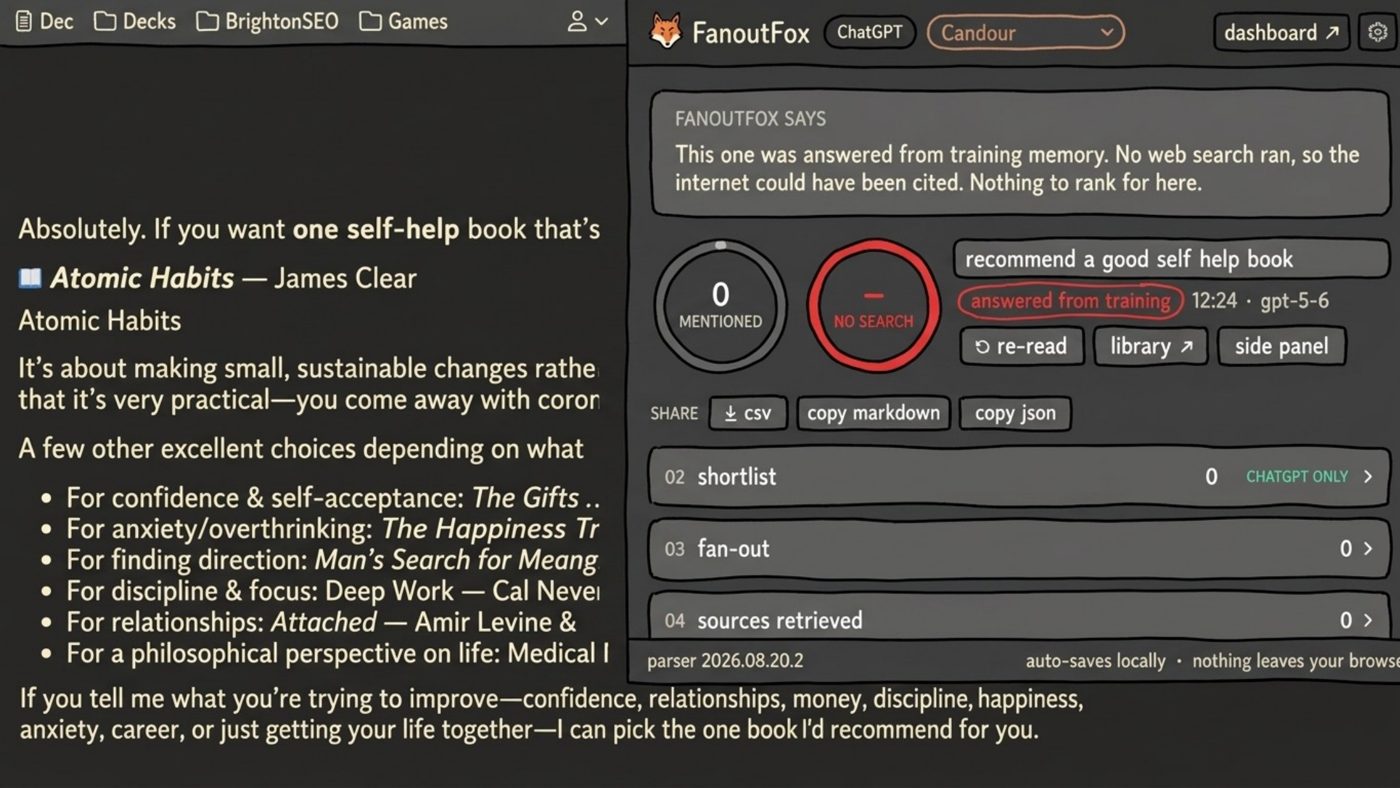
I requested it to advocate a great self-help e book (one other dependable technique to inform somebody works in search engine optimization). Considerably to my shock, the reply got here fully from coaching. No net search ran. ChatGPT was merely recommending books based mostly on what it had learn.
That’s genuinely helpful to know, as a result of it means it’s near unattainable so that you can affect that reply within the quick time period. If the response is coming from coaching knowledge, altering it’s a long-term mission, not one thing you repair with a brand new touchdown web page subsequent Tuesday. Realizing which of your goal prompts set off retrieval and which don’t tells you the place effort will repay now and the place it’s a gradual burn.
3. Reddit Didn’t Go Wherever
You’ll most likely have seen that Reddit is being cited far much less by ChatGPT. Petra Labs’ evaluation of 113,500 ChatGPT runs confirmed Reddit’s share of ultimate citations falling roughly 80% in a single day in mid-August 2026, shortly after GPT-5.6 grew to become the default mannequin.
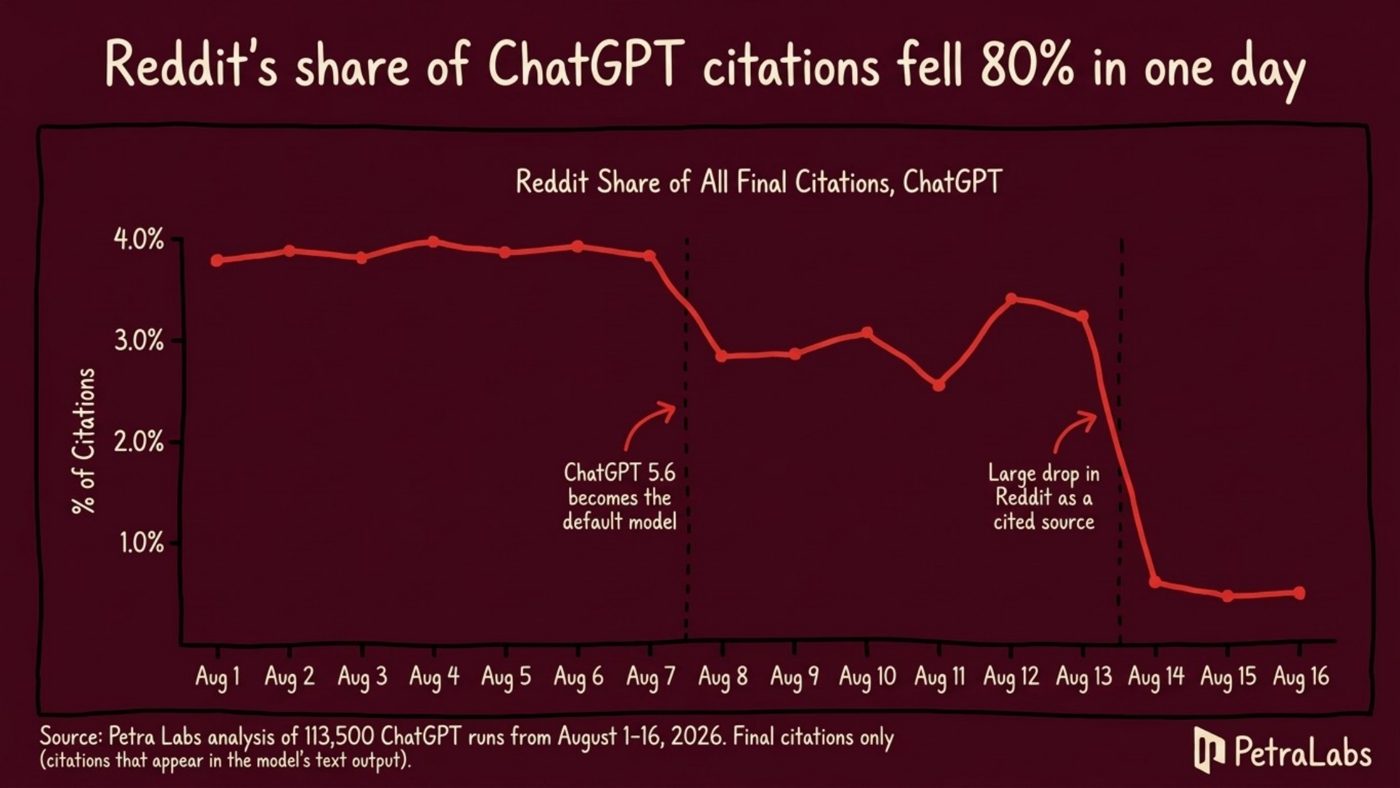
It will be very straightforward to have a look at that chart and conclude Reddit is not value bothering with for AI visibility. The community knowledge says in any other case. Suganthan’s analysis, and the info popping out of FanoutFox, confirmed that whereas Reddit is being cited an excellent deal much less, it’s nonetheless being used simply as a lot within the background. The most important change since GPT-5.6 is that the fan-out searches lean closely on web site: queries, and Reddit continues to be very a lot amongst them. ChatGPT continues to be studying what folks say on Reddit to determine whether or not to advocate a model. It has merely determined to quote the seller’s personal web page as a substitute of the thread.
That may be a aggressive benefit for anybody who is aware of it, and a entice for anybody who solely reads the quotation charts. It’s also a great instance of the qualitative perception that large quotation research are likely to miss: counting the hyperlinks in a solution tells you what the mannequin selected to indicate, not what it selected to learn.
However Wait, There’s Extra…
A number of takeaways to encapsulate the broad and particular:
This knowledge is functionally useful to your optimization. Realizing the freshness window to your subject, or that Reddit continues to be being learn, is just attention-grabbing till you employ it to determine what content material to construct, when to replace it, and the place to spend effort. Then it’s cash.
These techniques change frequently, and there’s a nice deal to study. The best way ChatGPT sends its community knowledge has modified radically over the previous few months, apparently at random. Suganthan has documented ChatGPT rebuilding its search instrument to the purpose the place the search_queries area he and I each relied on vanished fully. I publish about this lower than I used to, partly as a result of issues appear to alter shortly after folks publish about them. Make of that what you’ll.
Use the instruments that now exist. You don’t should be a developer to do any of this anymore. Perplexity Laptop can run the browsers, seize the visitors, and summarize what’s attention-grabbing. It may construct you a Chrome extension that you just load in two clicks. And FanoutFox will do a number of the ChatGPT studying for you, free of charge.
The information is all there, shifting between your browser and the backend each time you search. Most individuals by no means open the crates. You need to.
Extra Sources:
This publish was initially printed on Mark Williams-Prepare dinner.
Featured Picture: TippaPatt/Shutterstock

